The question takes ten minutes to answer — provided you avoid the mistake that skews everyone else’s result. And if the answer is no, the causes are identifiable, and most of them are fixable.
Why the test everyone runs returns a false result
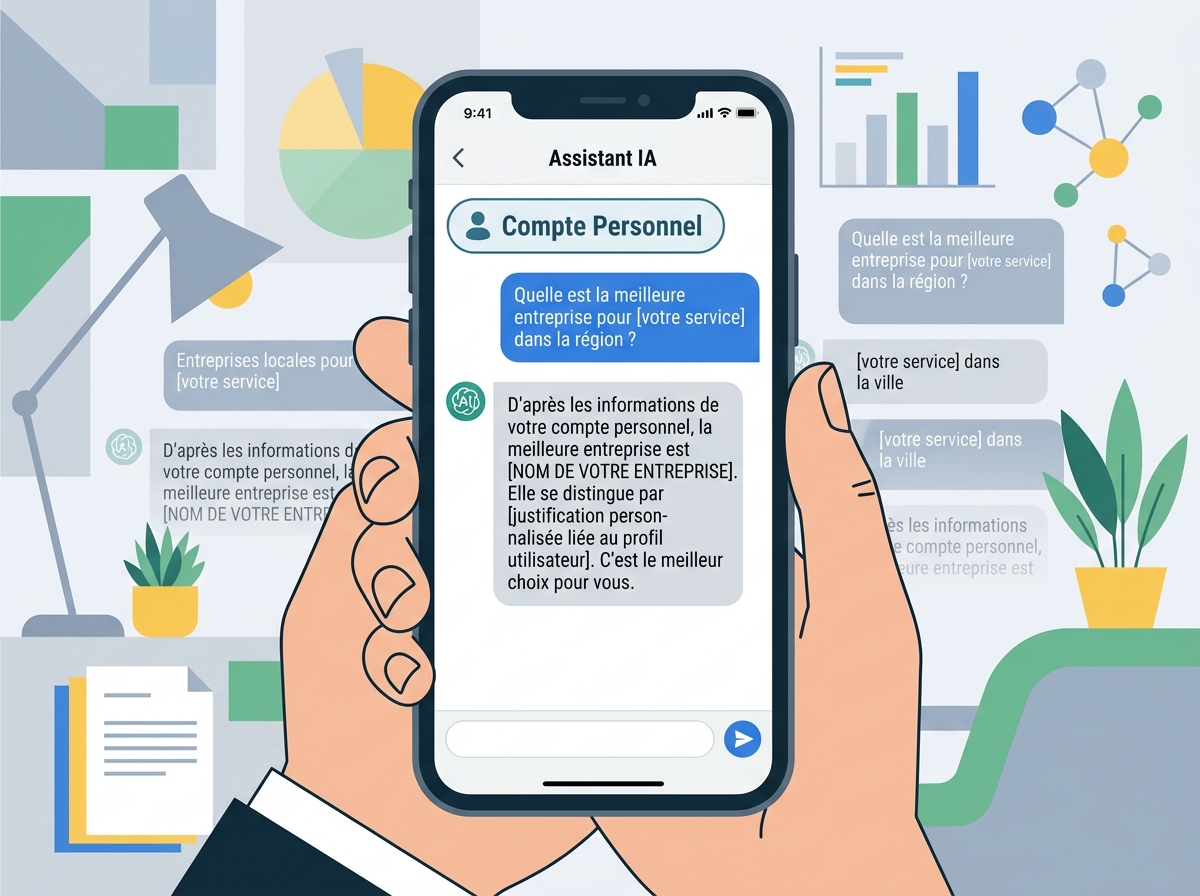
Clients increasingly ask whether they “show up in ChatGPT”. The question is a fair one: when a buyer asks an assistant for advice instead of working through ten links, being absent from the answer amounts to not existing for that journey.
But the way most people check produces an answer that is wrong, and reassuring.
Mistake 1 — testing from your own account
Assistants personalise: they take conversation history into account, sometimes account memory, and location. You have already talked to that assistant about your company, if only by typing its name into the question. It hands the name back to you.
You conclude that you are cited; a prospect who has never heard of you will get something else entirely.
Mistake 2 — asking “do you know this company?”
A model almost always answers yes to that shape of question, because it invites confirmation. The question that matters is the one a buyer actually asks: “which provider would you recommend for this need, in this city”.
The test that gives you something to act on
- Open a fresh conversation, in a private window, signed out of every account
- Ask from the buyer’s point of view, never naming the company
- Write five to ten variants: need, trade, city, budget constraint, urgency
- Repeat across at least three assistants — answers diverge sharply from one to the next
- Note who is cited in your place, and where the answer draws its sources from when it shows them
- Run it again a few days later: a single answer is not a measurement
These models are not deterministic: two runs of the same question can produce two different answers. Concluding from a single attempt is flipping a coin and calling it a trend.
A serious measurement repeats, across several phrasings and several days, and reasons in citation frequency rather than yes or no.
What the research identifies as the real levers
The reference work on this subject — Aggarwal and co-authors, « GEO: Generative Engine Optimization », KDD 2024, arXiv 2311.09735 — measured the effect of different content changes on visibility in generative answers. Two findings are worth knowing.
The first: the best methods improve visibility by up to roughly 41%, and among the most effective are adding citations and adding statistics. A page that cites its sources and carries verifiable figures is picked up significantly more than a page that merely asserts.
The second, and more counter-intuitive: simply adopting an authoritative tone, changing nothing else, produces no significant effect.
Writing “we are the experts” does not earn citations. Writing “according to this source, this figure” does.
The common causes of absence, in the order to address them
- No page answers the question the way a buyer asks it — you talk about your offer, they talk about their problem
- Your pages assert without citing: no source, no figure, no date, so nothing to pick up
- The company is described nowhere but on its own site — assistants lean heavily on third-party sources
- Information is inconsistent from one platform to the next: the model cannot tell which entity it is handling
- Too few reviews, or old ones: the reputation signal is weak
- Pages that crawlers read poorly — a page that cannot be reached is never a source
Measuring earns you no citations
These causes can be corrected, but none of them is corrected by writing “cited by AI” on your homepage. They call for work on content, on the consistency of your information, and on presence beyond your own site.
That is a project of several weeks, and its effect is measured exactly like everything else: a measurement before, an observation window, a measurement after.
A dashboard tells you that you are not cited; it does not rewrite your pages, fix your business profile or collect your reviews. Measurement is necessary, and never sufficient.